Local LLMs on NPU Laptops: Why the Market Me Global Lessons Work on Every AI
Published July 14, 2026 · by Emmanuel Abou Chabke
Local language models can run on your own computer when the model and software fit its hardware. Some supported workloads use an NPU; others use the CPU or GPU. The practical prompting skills taught in the Academy can transfer, but the result still needs testing on the model you choose.
The shift no one is explaining well
Local execution gives you another way to use a language model. Start by checking the model’s licence, memory requirements and supported runtime. The important question is whether the setup can perform your task reliably, not whether the computer carries an AI label.
But every one of those local models still speaks the same language: prompts. Role, context, constraints, examples, iteration. That is exactly what the Market Me Global lessons teach, and why they age well no matter which model you end up running.
What an NPU actually is
An NPU accelerates supported neural-network operations. It does not automatically accelerate every local LLM. Check the exact device, model and software backend together, and measure the performance of the task you intend to run.
Before buying hardware, try a suitable model on a computer you already own. Check memory use, response quality, loading time and which processor is doing the work. Keep sensitive information out of the test until you have reviewed storage, logs, network connections and telemetry.
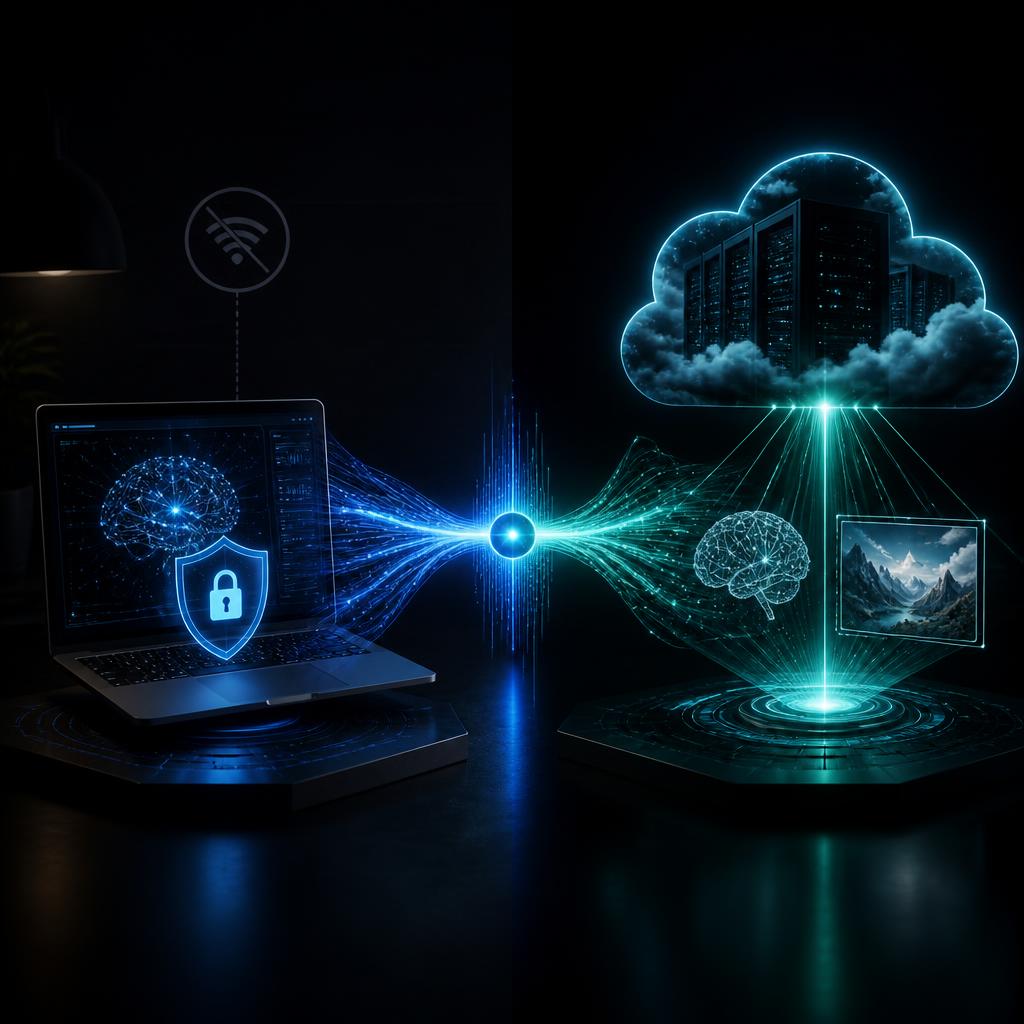
Every Market Me Global chapter teaches a portable idea, not a ChatGPT-specific trick. Here is how each lesson maps onto a local LLM.
Prompt structure (Role · Context · Task · Constraint · Example)
Local models are often smaller, which means they benefit even more from tight structure. The exact framework taught in Chapter 1 lifts a 7B Llama 3 response from mediocre to a result you can evaluate against your requirements.
Iteration loops
The 'critique → rewrite → verify' loop from Chapter 2 is model-agnostic. Ollama, LM Studio and Windows AI Foundry all support system prompts and multi-turn chat, so the loop runs identically offline.
Private data workflows
Chapter 3's data-handling patterns become far more valuable locally: client briefs, contracts, financials and PII never leave your machine. Same prompts, zero cloud exposure.
Hybrid stacks
The Bundle shows how to route work: local for high-volume drafting, cloud for reasoning-heavy tasks and image generation. One skillset, two engines.
Choose a local stack by compatibility
- Runtime: choose software that supports your operating system and intended model format.
- Model: check the licence, memory requirement, context limit and suitability for the task.
- Acceleration: verify the supported CPU, GPU or NPU backend rather than assuming one is active.
- Prompt library: reuse the task structure, then retest the prompt and checking rules.
- Fallback: decide what happens when the model cannot produce a reliable answer.
What this means if you're just starting
You do not need to pick a model first. Pick the skill. Learn to think with LLMs, and every new engine, cloud or local, 7B or 400B, becomes a tool you already know how to drive. That is what every chapter in the academy is built around.
Start with 3 free minutes a month inside the portal. Top up any time you want, or unlock a full chapter / the bundle once you decide this is the direction you want to go.
FAQ
Do the Market Me Global lessons work with local LLMs like Llama 3, Mistral or Phi?
Yes. The lessons teach model-agnostic thinking, role, context, constraints, examples, and iteration. Those prompting patterns can transfer to cloud and local models, but you should retest instructions and check the software’s supported hardware backend.
What is an NPU and why does it matter for LLMs?
An NPU is a processor designed to accelerate supported neural-network operations. Whether a language model uses it depends on the model, runtime and device; local inference may instead use the CPU or GPU.
Is a local LLM good enough to replace ChatGPT for marketing work?
Test the actual drafting or extraction task. A local model may meet your needs, but accuracy, context limits and speed vary. Compare with your requirements and check privacy settings rather than assuming either local or cloud always wins.
How much does it cost to run a local LLM?
Local inference may avoid a hosted per-token fee, but hardware, electricity, setup and optional software still have costs. Check the model’s memory needs and software support on your actual device.
One skillset. Every model.
Learn the lessons once and use them on ChatGPT, Claude and every local LLM your computer can support.
Test your actual model before buying new hardware
Check the software’s supported acceleration backend, model format and memory requirements. A local model may run on the CPU or GPU even when the laptop includes an NPU. Measure the tasks you need, including loading time and response quality. Local execution can reduce the need to send inputs to a cloud service, but you still need to inspect downloads, telemetry, logs and any network-connected features.
Try this example
Try a small, non-sensitive summary task on hardware you already own. Note which processor the software uses, whether the model fits in memory and how much correction the answer needs. Compare that experience with your requirement before treating an advertised chip capability as a reason to buy a laptop.
Check your result before the next step
- Confirm model and backend support with the software and hardware documentation.
- Measure the real task rather than comparing chip labels alone.
- Inspect network use, logs and storage before assuming the workflow is private.
One more question, answered
Does an NPU laptop automatically run every local LLM on the NPU?
No. Acceleration depends on the model and software backend. Some workflows use the CPU or GPU instead. Verify compatibility and test the intended task before buying hardware.
Continue with the model-independent prompting workflow to put this guide into practice.